AI Model Routing: Why the Orchestration Layer Is the Next Big Play Next to the Labs
TL;DR
AI model routing and orchestration decide which model handles which task. How routing differs from orchestration, and practical ways to cut your model spend.
Last updated: June 17, 2026
Official Sources#
| Topic | Source |
|---|---|
| $500M one-month enterprise Claude bill | cybernews.com |
| Anthropic run-rate and enterprise spend | Inc. / Fast Company |
| GLM-5.2 benchmarks and cost | VentureBeat, InfoWorld |
| Factory Router | factory.ai/news/factory-router |
| Perplexity / Aravind Srinivas on orchestration | 20VC, Fortune |
A short version for people who are budgeting right now: most of your tasks do not need a frontier model. The work that decides which model handles which task, and reserves the expensive model for the hard minority, is where the cost savings and the defensibility now live. This post is about that layer, why it is suddenly worth building on top of, and how to start cutting your own spend.
The $500M wake-up call#
In late May 2026, reports surfaced that an enterprise client ran up roughly a $500 million Claude bill in a single month because it never set per-employee usage caps. Engineers pointed agents at frontier models, the agents looped, and nobody put a ceiling on any of it (cybernews). That is an extreme case, but it is not an isolated one. Uber reportedly burned through its entire 2026 AI budget by April. Microsoft scaled back Claude Code licenses. Anthropic is at roughly a $30 billion annualized run-rate, up from about $9 billion at the end of 2025, with more than 1,000 companies spending over $1M a year (Inc.).
Read those numbers together and a pattern jumps out. The labs are not the ones with a cost problem. They are the ones collecting the bill. The cost problem belongs to everyone building on top of them, and it is getting worse precisely because frontier models are good enough that teams reach for them by default, for everything, without asking whether the task actually needs that horsepower.
That default is the expensive habit. And the thing that fixes it is not a cheaper frontier model. It is a layer that decides, per task, whether you need the frontier model at all.
The cost gap is now too big to ignore#
For a while the argument for always using the best model was simple: the open and cheap models were not good enough for real work, so the price difference did not matter. As of June 2026 that argument is dead.
On June 16, Z.ai released GLM-5.2, a 753-billion-parameter open-weights model under an MIT license. On SWE-bench Pro it scored 62.1, ahead of GPT-5.5 at 58.6 on a long-horizon autonomous coding benchmark. It does this at roughly one-sixth the per-token cost (VentureBeat, InfoWorld).
Sit with that. An open-weights model you can run yourself, or rent for a fraction of the price, beats a frontier proprietary model on a hard agentic coding benchmark. The quality argument for routing everything to the most expensive option no longer holds. When the cheap model is sometimes the better model, paying frontier prices for every token is not caution, it is waste.
This is the structural shift. The performance curves of open and frontier models have converged enough that the interesting question is no longer "which single model is best." It is "which model is best for this specific task, at this moment, given what it costs." That is a routing question, and routing questions need a routing layer.
Router versus orchestration: a distinction that matters#
People use "routing" and "orchestration" interchangeably, and they should not. The difference is the whole point of this post.
Routing picks a model per request. Same task, one model, chosen well. It is a substitution problem: given this prompt and these constraints, which model gives me the best result per dollar? Do the substitution invisibly and the user never knows or cares which model answered.
The cleanest current example is Factory Router. It routes each Droid coding session across models and providers - Claude, DeepSeek, and others - choosing the optimal model per task from a pool of frontier and efficient options. Factory reports roughly 20-25% token savings while holding frontier-level performance, and 99.9%+ request reliability through failover: if a model struggles, the session escalates to a more capable one, and if a provider path goes down, the session keeps running through a healthy path. The droids are model-agnostic and the system is self-learning. That is routing done well - quietly swapping the cheaper model in wherever it is good enough, escalating only when it is not.
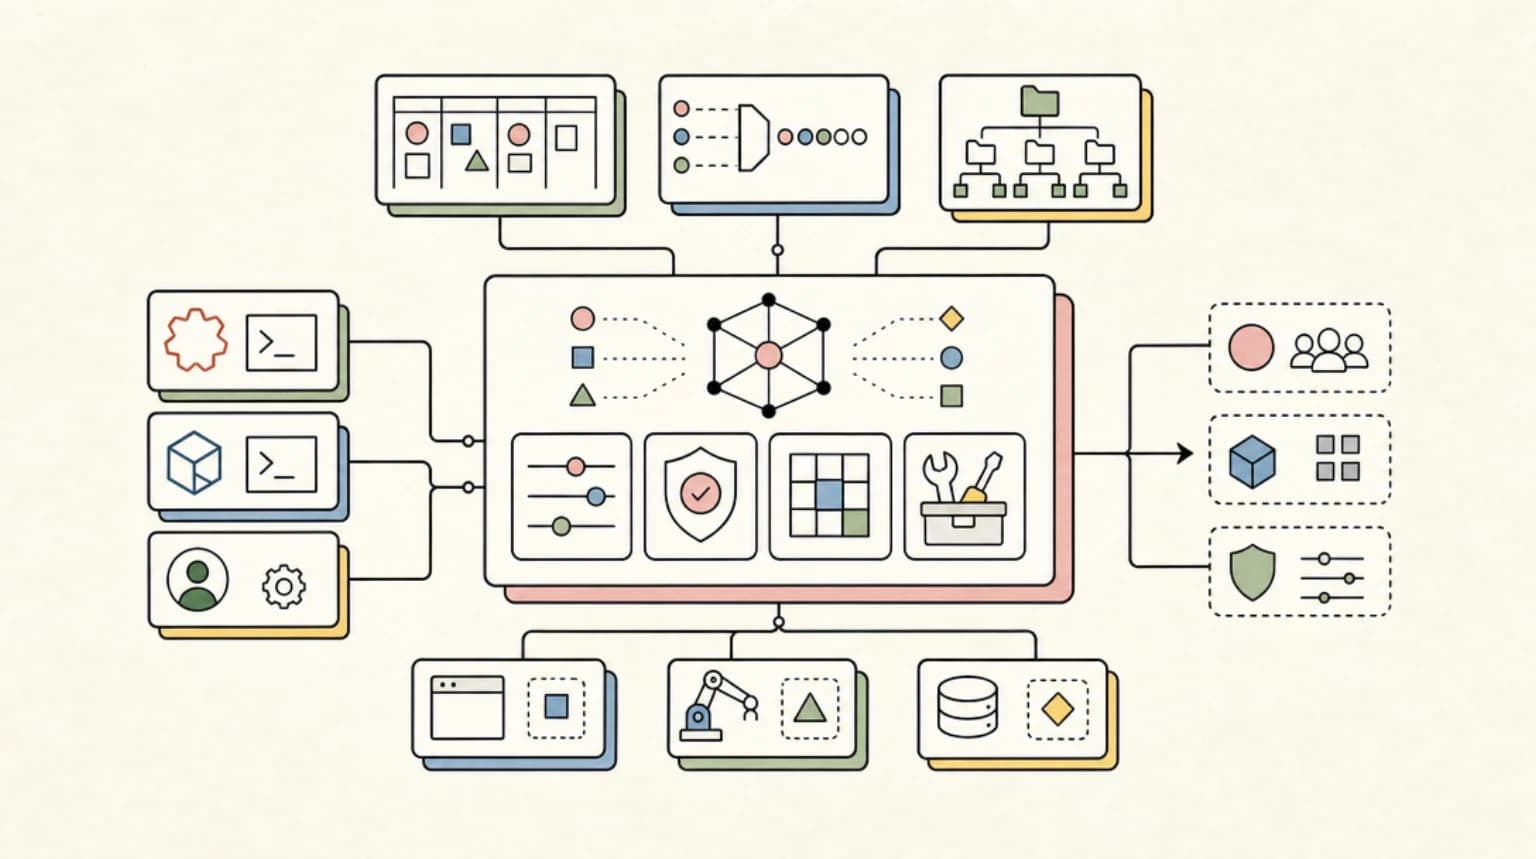
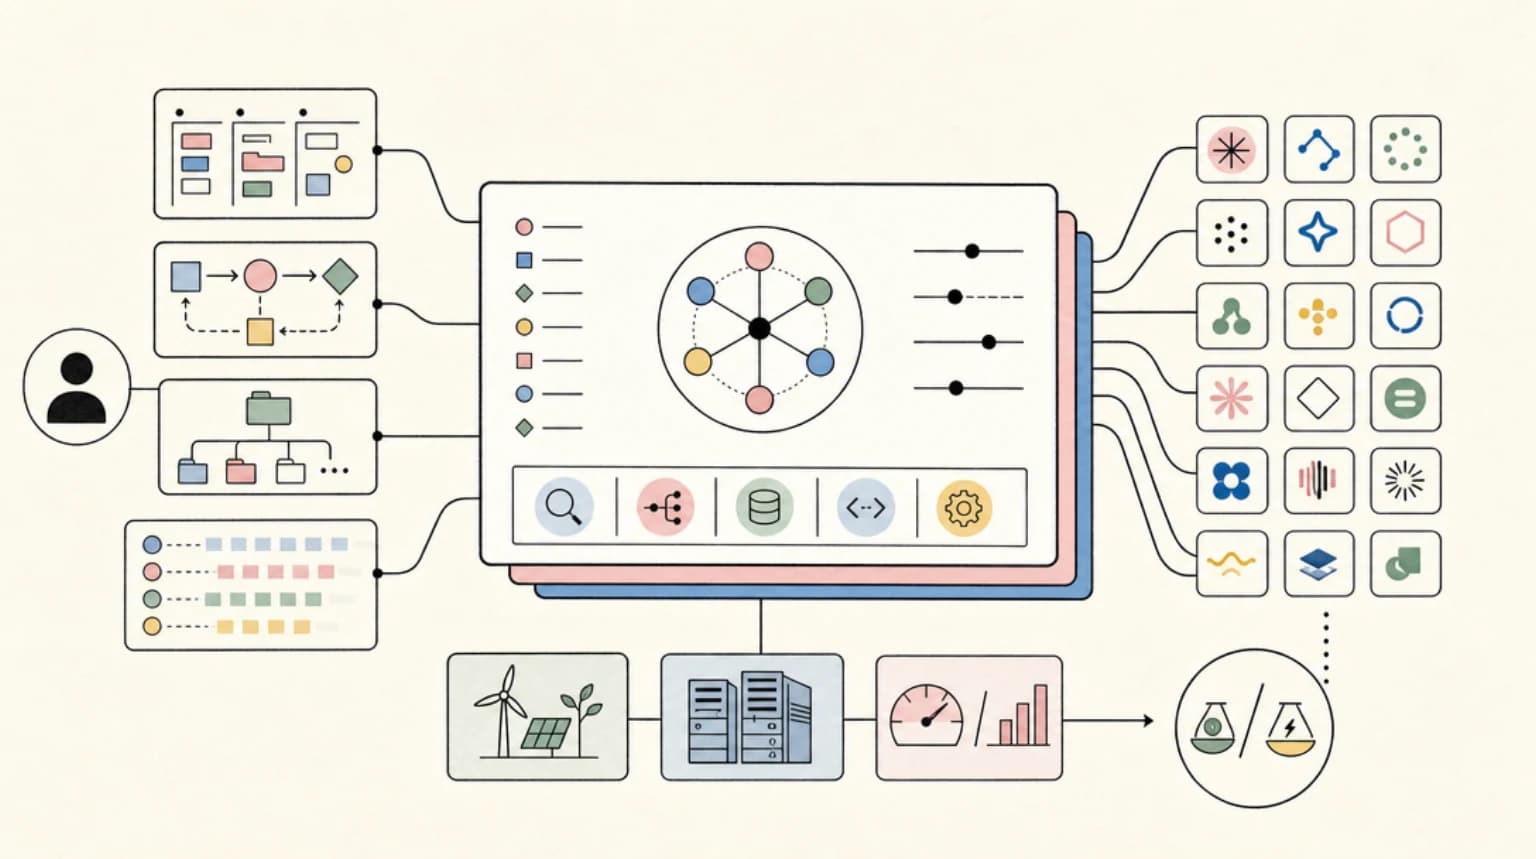
Orchestration is a larger claim. It does not just pick a model, it decides how the work itself is decomposed: which model, how many agents, how they collaborate, what runs locally versus in the cloud, when to call a tool versus call a model. Routing is a subroutine inside orchestration.
Perplexity's Aravind Srinivas has been the loudest voice here. On Harry Stebbings' 20VC he put it bluntly: "The orchestration is the product. The model is a tool." Perplexity's "Computer" agent does not just route to the cheapest acceptable model. It orchestrates which model handles which sub-task, how multiple agents coordinate, and whether work runs on-device or in the cloud - what Srinivas calls an "omni agent" rather than a router (Fortune, 20VC). His preferred metric tells you everything about where his head is: not tokens, not latency, but "token value per watt per user" - useful output, normalized by energy and by person. That is an orchestration metric, not a routing one.
The short way to hold the two apart: routing optimizes the choice within a fixed shape of work. Orchestration optimizes the shape of the work itself. Factory Router is best-in-class at the first. Perplexity's Computer is aiming at the second.
The thesis: orchestration is the play next to the labs#
Here is the argument. The labs are going to keep winning the model race, and they are going to keep capturing enormous revenue doing it. You are not going to out-train Anthropic or OpenAI, and you should not try. But the labs have a structural blind spot, and it is the same one that produced the $500M bill: they make money when you use more of their most expensive model, so they are not the party with the strongest incentive to help you use less of it.
That misaligned incentive is the opening. The orchestration layer wins by doing the thing the labs are not motivated to do: route the cheap, open, good-enough model for the roughly 80% of tasks that do not need frontier reasoning, and reserve the frontier model for the hard 20% where it actually changes the outcome. The value created is the delta between the all-frontier bill and the orchestrated bill, and as the cost gap widens - GLM-5.2 at one-sixth the price is just the latest data point - that delta gets bigger every quarter.
This is a defensible place to build for a few reasons:
- It is model-agnostic by design. A good orchestration layer gets more valuable as more models exist, because it has more options to route between. New model releases are tailwinds, not threats. Contrast that with building a thin wrapper on one model, where the next release can erase you.
- It compounds with data. Every routed task is a labeled example of "this kind of work, sent to this model, produced this result at this cost." That feedback loop - which Factory describes as self-learning - is a moat that the labs do not have access to, because they only see their own model's traffic.
- The incentives are aligned with the customer. You make money by saving the customer money. That is a far easier sale in a year when finance teams are looking at AI line items the size of the $500M bill.
The labs sell horsepower. The orchestration layer sells judgment about when you need it. In a world where horsepower is abundant and cheap horsepower is suddenly competitive, judgment is the scarce thing.
What a routing decision actually looks like#
The decision is less mysterious than it sounds. At its core it is a classifier in front of your model call. Here is the shape of it in pseudo-code, with the escalation pattern Factory uses baked in:
def route(task):
    # 1. Cheap, fast triage - estimate task difficulty
    difficulty = classify_difficulty(task)  # a small/cheap model or heuristic

    # 2. Route the easy majority to the cheap, good-enough model
    if difficulty < THRESHOLD:
        result = call_model("glm-5.2", task)        # ~1/6 the cost
        if quality_ok(result, task):
            return result
        # 3. Escalate only on failure - the hard minority
        return call_model("frontier-model", task)   # reserved for the 20%

    # 4. High-difficulty tasks go straight to frontier
    return call_model("frontier-model", task)
Three ideas do most of the work here. First, triage cheaply - the classifier deciding difficulty should itself be small or heuristic, or you have just moved the cost, not removed it. Second, default to cheap and escalate on failure rather than defaulting to frontier and hoping. Third, measure quality, because the whole scheme depends on knowing when the cheap model was not good enough. Without a quality signal you are flying blind, and silent quality regressions are how routing projects lose trust.
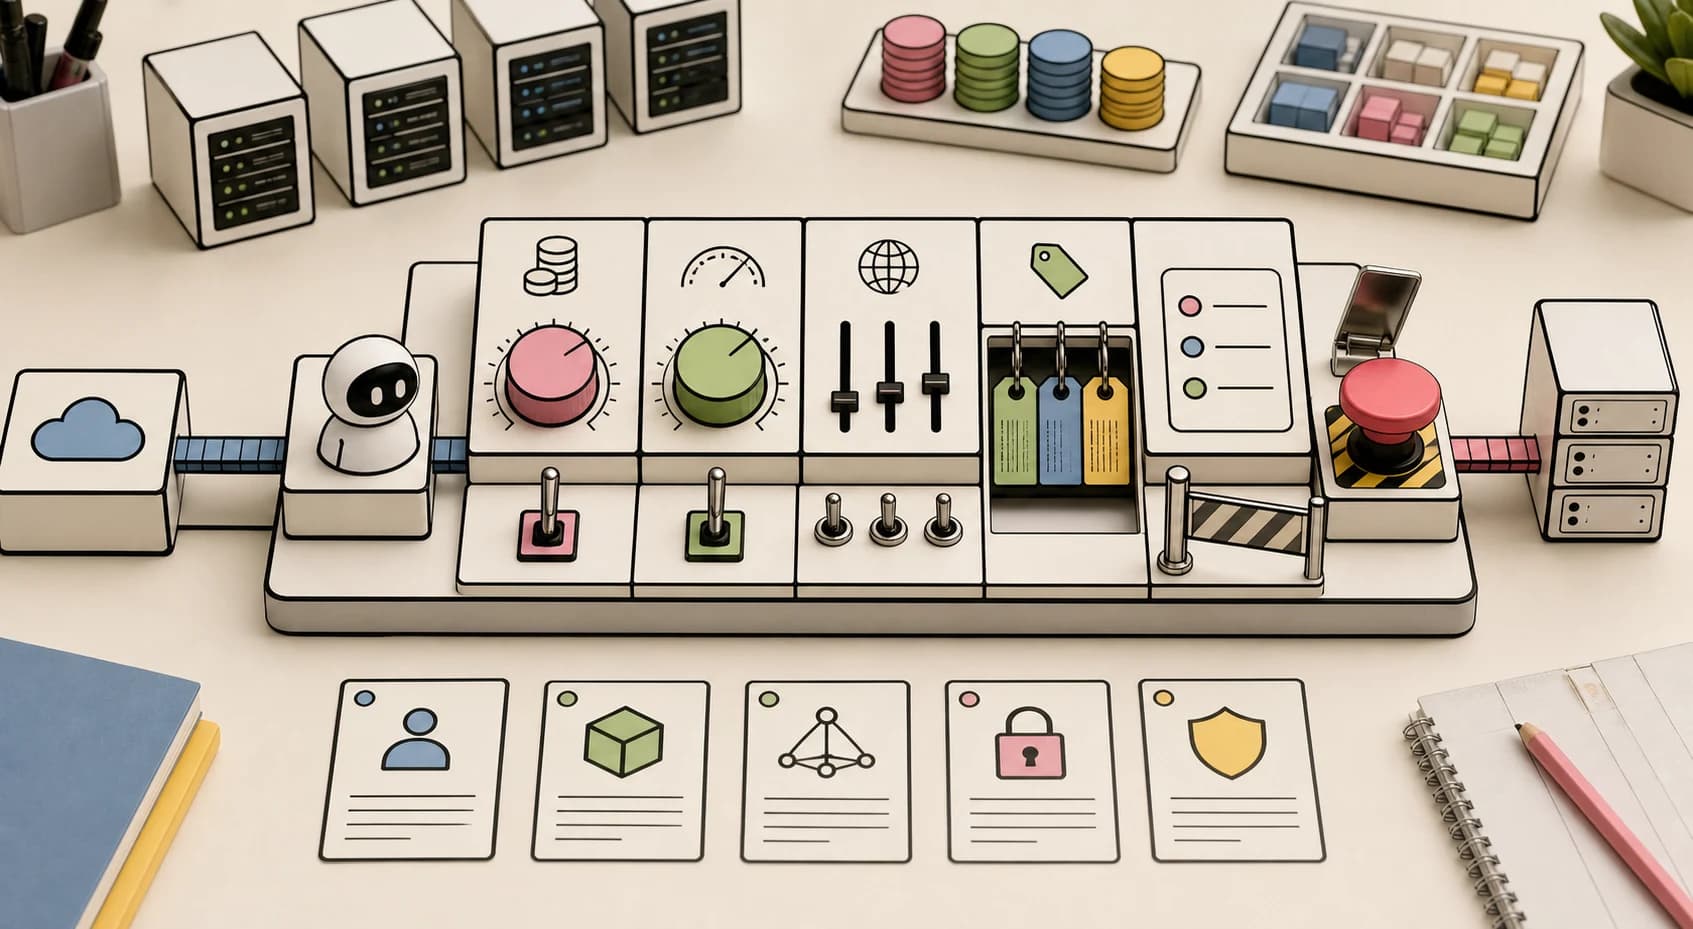
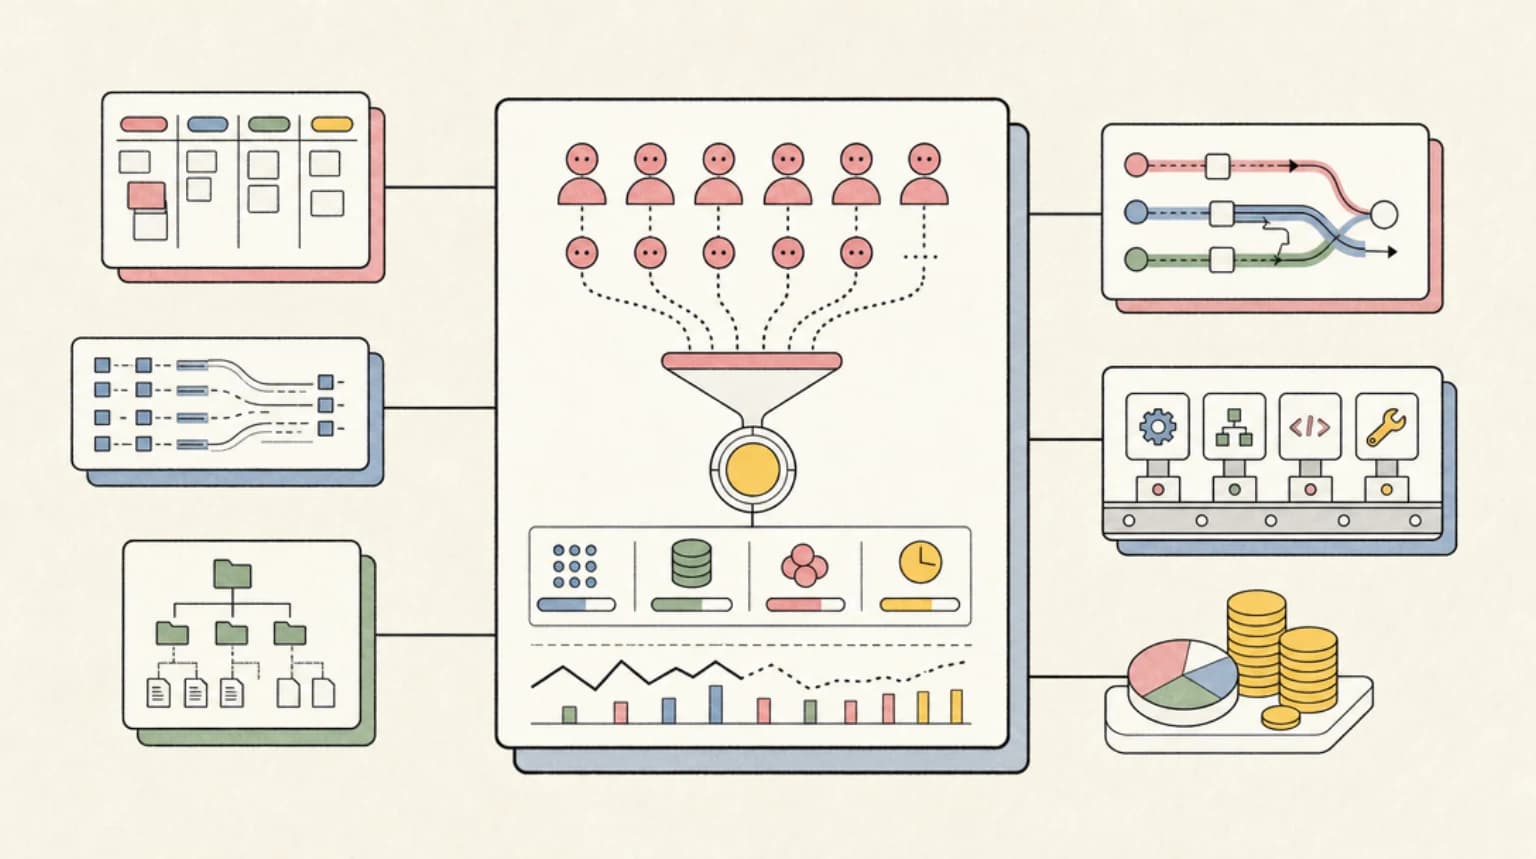
Orchestration extends this. Instead of one task and one model choice, you decompose a job into sub-tasks, route each one, run some in parallel, run some locally to save on tokens and latency, and have one agent check another's output before you accept it. The routing decision above is the atom. Orchestration is the molecule.
Practical takeaways for cutting your spend#
You do not need to build Perplexity's Computer to benefit from this. In rough order of effort and impact:
- Set hard caps first. Before anything clever, put per-user and per-project dollar ceilings in every provider dashboard. The $500M bill happened because nobody did this. Caps are not optimization, they are the seatbelt. (We went deep on this in The $400 Overnight Bill.)
- Measure your task mix. You almost certainly do not know what fraction of your calls genuinely need a frontier model. Log task type and outcome for a week. Most teams find the frontier-required share is well under half.
- Adopt a router before you build one. If you are running coding agents, a tool like Factory Router gives you 20-25% savings with failover reliability and no engineering effort. Buy the obvious win before you build the bespoke one.
- Default to open-weights for the majority. With GLM-5.2 beating GPT-5.5 on SWE-bench Pro at one-sixth the cost, the cheap path is no longer the inferior path for a large class of work. Make the cheap model the default and escalate, not the other way around.
- Build a quality gate. Routing without a quality signal is gambling. Even a coarse check - does the code compile, does the test pass, does a cheap judge model approve - lets you escalate intelligently instead of blindly.
- Track value, not tokens. Srinivas's "token value per watt per user" is a useful north star. The goal is not minimum tokens, it is maximum useful output per dollar. A router that saves tokens but tanks quality is not saving you anything.
The labs built the engines. The interesting work now is in the layer that decides which engine to start, and when to leave it off. As the bills climb and the cheap models get good, that layer stops being a nice-to-have optimization and starts being the product.
Frequently Asked Questions#
What is AI model routing and how does it save money?#
AI model routing is a layer that picks which model handles each request based on the task's difficulty and cost. Instead of sending every prompt to the most expensive frontier model, a router sends the easy majority to a cheaper or open-weights model and reserves the frontier model for the hard minority. Factory Router, for example, reports 20-25% token savings on coding sessions while holding frontier-level performance. The savings scale with the cost gap between models, which is widening as open-weights models like GLM-5.2 reach frontier-level quality at a fraction of the price.
What is the difference between model routing and orchestration?#
Routing picks the best model for a single request - it optimizes the choice within a fixed shape of work. Orchestration is larger: it decides how the work itself is decomposed, how many agents run, how they collaborate, what runs locally versus in the cloud, and when to call a tool versus a model. Routing is a subroutine inside orchestration. Factory Router is a strong example of routing; Perplexity's "Computer" agent, which its CEO describes as an "omni agent," is aiming at full orchestration.
How do I cut my Claude or frontier-model API bill?#
Start with hard per-user and per-project spend caps in your provider dashboard - the reported $500M one-month Claude bill happened because none were set. Then measure what fraction of your calls actually need a frontier model; most teams overestimate it. Adopt a router to automatically send easy tasks to cheaper models, default to open-weights models for the majority of work, and build a quality gate so you escalate to the frontier model only when the cheap one falls short.
Is an open-weights model good enough to replace a frontier model?#
For a large and growing class of tasks, yes. As of June 2026, Z.ai's open-weights GLM-5.2 scored 62.1 on SWE-bench Pro, ahead of GPT-5.5 at 58.6, at roughly one-sixth the per-token cost. The right approach is not all-or-nothing: route the easy majority of tasks to the cheaper model, measure quality, and escalate to a frontier model only for the hard minority where it changes the outcome.
Why is the orchestration layer a good place to build a company?#
The labs profit when you use more of their most expensive model, so they have little incentive to help you use less of it. That misalignment is the opening. An orchestration layer is model-agnostic, so it gets more valuable as more models are released rather than being threatened by them. It compounds with data - every routed task teaches it which model fits which work - and its incentives are aligned with the customer because it makes money by saving the customer money. In a year of escalating AI bills, that is an easy sale.
Continue Reading#
- TypeSafe Jev: the First Decision-Only Model Class - a $0.042/MTok decision model that changes which work routers send to string models
- Change2Task: The Assembly Line for Coding Agent Training Data
- Claude Agent SDK Credits End the Subscription Arbitrage
- 'The Orchestration Is the Product': What Perplexity's Aravind Srinivas Sees That the Model Labs Don't
- OpenRouter - a hosted router with published pricing and limits
- Where to Access AI Models - official APIs, routers, and gateways compared
Get the next deep dive like this in your inbox
One email a week on AI Model Routing and the rest of the AI dev stack. Free.
Read next on local and open-weight models
The $400 Overnight Bill: Why Managed Agents Need FinOps Now
Five managed-agent providers, five pricing models, zero unified cost attribution. If you're running agents overnight, you need FinOps you don't have yet.
13 min readOmnigent: Databricks' Meta-Harness for Orchestrating Claude Code, Codex, and Custom Agents
Omnigent is a Databricks meta-harness above Claude Code and Codex that keeps sessions, policies and skills portable. What it does and how to install it.
8 min readAI Coding Tools Pricing Comparison 2026
AI coding tools pricing, verified Sep 28, 2026: Claude Code, Codex, Cursor, Copilot, Antigravity, Windsurf and more. Free tiers, pro plans and hidden costs.
12 min readNew here? Start with
Technical content at the intersection of AI and development. Building with AI agents, Claude Code, and modern dev tools - then showing you exactly how it works.